Kevin Rodriguez
I build systems that are fast, clear, and maintainable. Currently at Cornell and working on agent orchestration and resource management.
Currently working on
Local Multi-Agent Loop
Two Qwen 27B agents sharing a pair of 3090s, working through a ~140-task plan to find, reproduce and fix bugs in open-source ML repos. The interesting part is everything around the model: a task tree so each step knows where it sits, short handoff notes when an agent stops, and a move to llama-server that took prompt-cache reuse from 7% to 97%. A second agent on the same GPUs bought about 20% more throughput.
294 runs · 89 agent-hours · 8.9M tokens generated
Recent experiment
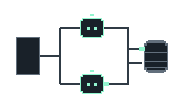
Speculative Decoding for Agent Workloads
Smaller models draft agent output; a target checks each block. Held-out prediction tests and a corrected decoder, with the speed comparison still pending.
Read the report →